Aurora DSQL: The Distributed SQL Database That Finally Stops Pretending Cross-Region Consistency Is Free
The Problem Nobody Wants to Admit They Have
Let me set the stage with something you’ve probably experienced but never quite articulated in polite company. You’ve built an application that works flawlessly in a single region. Your queries are snappy. Your transactions are predictable. Life is good. Then your boss asks the question that makes senior engineers reach for their stress ball: “What happens if that region goes down?” And suddenly you’re staring at a problem that looks simple on a whiteboard but becomes catastrophically complex when you actually try to solve it.
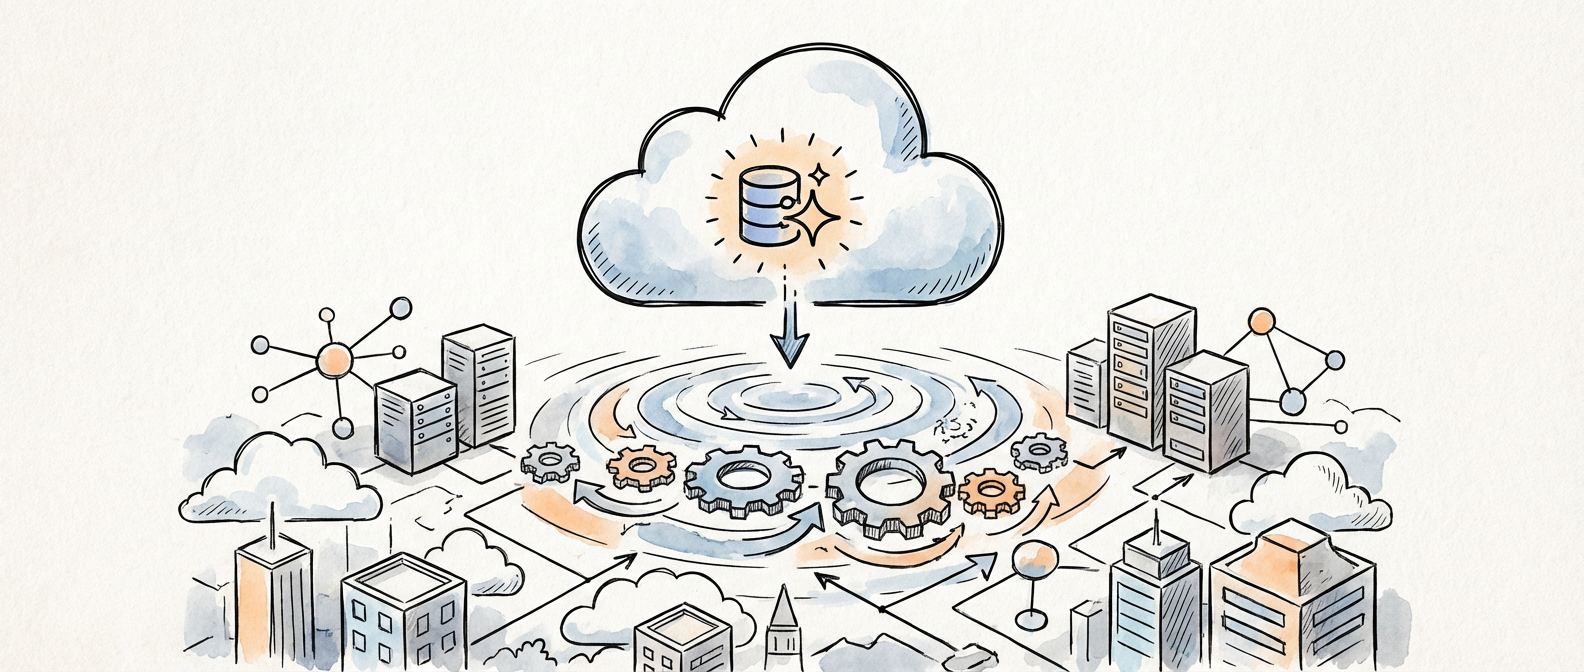
Traditional databases weren’t designed for what we actually need anymore. They were built on the assumption that all your data lives in one place, maybe with some read replicas sprinkled around for performance. Multi-region active-active scenarios? That’s where things fall apart. You’re managing consistency across network boundaries. You’re dealing with split-brain scenarios. You’re writing application logic that would make your younger self weep. And despite all that complexity, you’re still taking a hit on latency because your writes have to serialize through a primary region.
This is the specific problem that distributed SQL databases were born to solve. But here’s where I need to be honest: most implementations felt like they were solving the problem while also introducing three new ones. They required different operational thinking. They demanded a different mental model for transactions. They often came with price tags that made CFOs nervous and architectures that made ops teams schedule extra therapy sessions.
What Amazon Actually Built This Time
At AWS re:Invent in December 2024, Amazon announced Aurora DSQL, and this is where I need to pump the brakes on my usual skepticism. They didn’t just slap a distributed label on Aurora and call it a day. They fundamentally rethought how a distributed database handles concurrency and durability, and the specifics matter more than the marketing copy suggests.
Aurora DSQL is a true active-active distributed SQL database, which means every region can accept writes simultaneously without needing to route everything through a primary. It delivers 99.999% multi-region availability without requiring read replicas, which is genuinely different from how you probably think about database failover today. But here’s where the real engineering thinking shows up: instead of using the traditional multi-version concurrency control that most databases lean on, Aurora DSQL implements an optimistic concurrency control model paired with an external transaction log that lives separately from storage.
What does that actually mean for you writing code at midnight trying to debug a production issue? It means write latency drops by up to 40% in cross-region scenarios compared to traditional MVCC implementations. That’s not a marketing number pulled from an ideal benchmark. That’s the difference between your writes taking 50 milliseconds and taking 80 milliseconds across continents. In high-throughput systems, that compounds into something significant. You can read more about how they’re approaching this on the AWS re:Invent 2024 Aurora DSQL announcement page.
When Pricing Becomes Part of the Architecture
Aurora DSQL reached general availability in Q1 2026 across four AWS regions, and the pricing starts at $0.50 per DPU-hour. For context, that’s positioning Aurora DSQL directly in competition with CockroachDB Dedicated and Google Cloud Spanner, which is exactly where Amazon wants to play. This isn’t a budget option. This is a tool for teams that have already decided they need distributed SQL and are evaluating where to build it.
The competitive landscape matters here because it clarifies what problem you’re actually solving. Google Cloud Spanner maintains a 99.999% SLA across multi-region configurations and processes over 2 billion requests per second across all its customers. That’s the bar Amazon is trying to reach. They’re not trying to be cheaper or simpler. They’re trying to be as reliable and capable, but with the operational familiarity of tools that AWS developers already know.
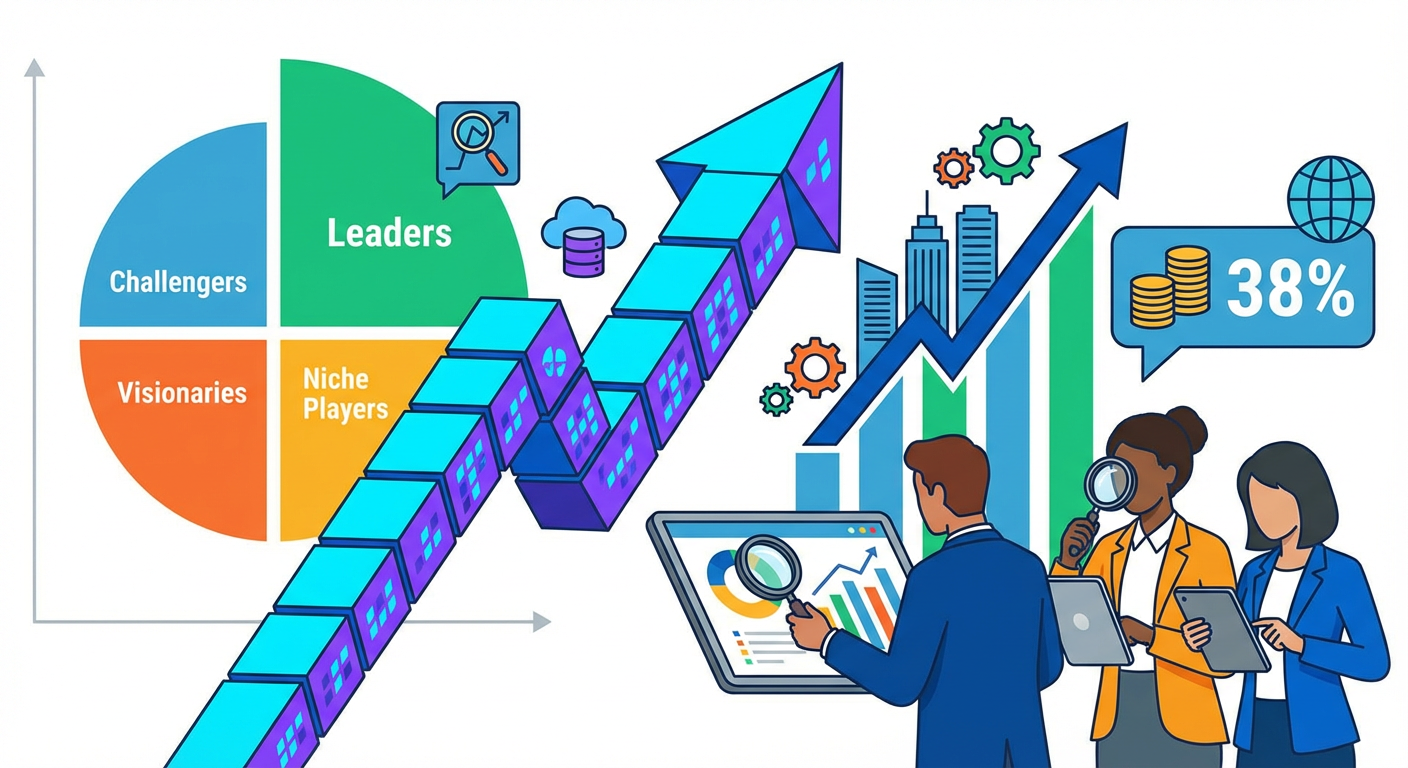
What’s interesting for your immediate decision-making is that analyst firms are paying attention to exactly this space. Gartner’s 2025 Magic Quadrant for Cloud Database Management Systems highlighted distributed SQL as the fastest-growing segment, with adoption increasing 38% year-over-year among Fortune 500 companies. Translation: this isn’t niche anymore. Your competition is probably already evaluating it or has already made a move.
Where You Actually Start Building
Here’s the thing that matters most if you’re thinking about whether Aurora DSQL fits your current architecture: you don’t need to do a dramatic rewrite to get value from it. If you already know Aurora SQL, the query language and transaction model are familiar. You’re not relearning fundamentals. You’re adding a capability you probably needed anyway.
The beginner’s approach here is deliberate. Start by identifying where your current single-region database is the bottleneck. Is it write latency across regions? Is it the operational complexity of managing read replicas? Is it the fact that a regional outage means actual downtime instead of graceful degradation? Once you’ve named the specific problem, Aurora DSQL becomes easier to evaluate. You can run a proof-of-concept with your actual workload pattern. You can measure the specific latency improvements. You can calculate whether the per-DPU-hour cost makes sense for your traffic pattern.
The mistake teams make is treating distributed SQL as a replacement for everything. It’s not. It’s a specialized tool for a specific class of problem: applications that need strong consistency across regions, accept that cross-region writes will never be instantaneous, and would rather pay for a managed solution than spend engineering cycles building and operating their own distribution layer.
The Architecture Conversation You’re About to Have
Whether you adopt Aurora DSQL or choose a different path, the conversation you need to have with your team is structural. Distributed SQL is now mature enough and accessible enough that the barrier to adoption isn’t technical anymore. It’s organizational. It’s about whether your ops team is ready to think differently about consistency models. It’s about whether your application layer can handle the latency characteristics of distributed writes. It’s about whether your team has the time and headspace to properly evaluate a new tool or whether you’re already stretched too thin.
You can explore the full feature set and documentation over at the Amazon Aurora DSQL product page. Start there if you want specifics about replication lag, transaction semantics, or regional availability. But before you dive into the technical deep-end, spend time with your team mapping out what multi-region actually needs to mean for your application. The technology is solid. The question is whether it solves your actual problem or just a problem you think you should have.
What’s your current biggest headache with regional failover? I’d genuinely like to hear what’s broken in your world right now. Drop a note in the comments or shoot me a message. The distributed SQL space is moving quickly, and real-world constraints beat hypothetical architectures every single time.

How to Share Files Through iCloud Drive Without the Usual Headaches
Why iCloud Calendar Sync Fails and How to Fix It
The Great Convergence: How Edge Computing is Reshaping Real-Time Data Architectures
About Author
